ECCV 2026
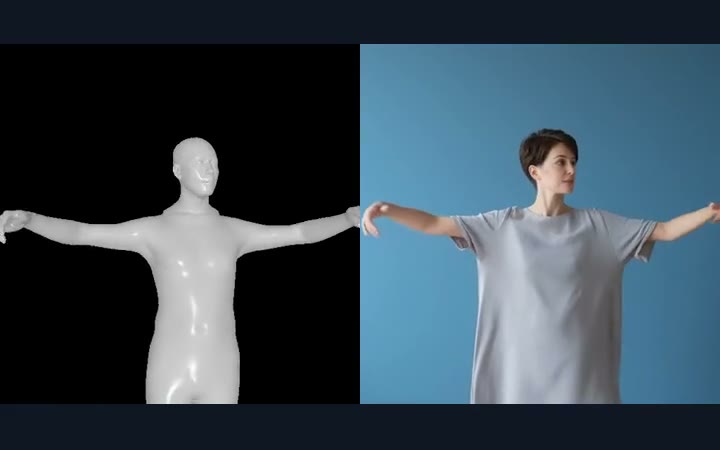
EMOSH: Expressive Motion and Shape Disentanglement for Human Animation
Mesh-guided human animation with motion–shape disentanglement, preserving the target’s identity and body shape.
I work on the GWM (Generative World Model) team at XPeng  , with research interests in world models, video generation, and 3D vision.
I received my M.S. in Electronic Information (Artificial Intelligence) from Tsinghua University  in 2026, advised by Prof. Haoqian Wang. I earned my B.Eng. in Robot Engineering from South China University of Technology
 .
Video generation, human avatars, and 3D reconstruction.
Mesh-guided human animation with motion–shape disentanglement, preserving the target’s identity and body shape.
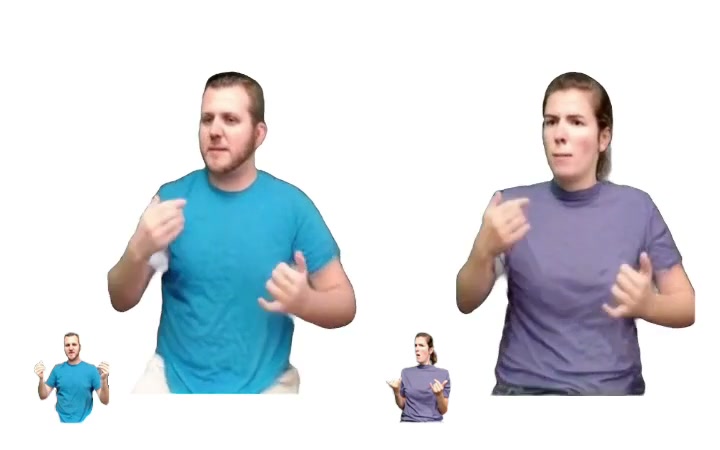
From a single image to an animatable upper-body 3D Gaussian avatar, with expressive motion and novel views.
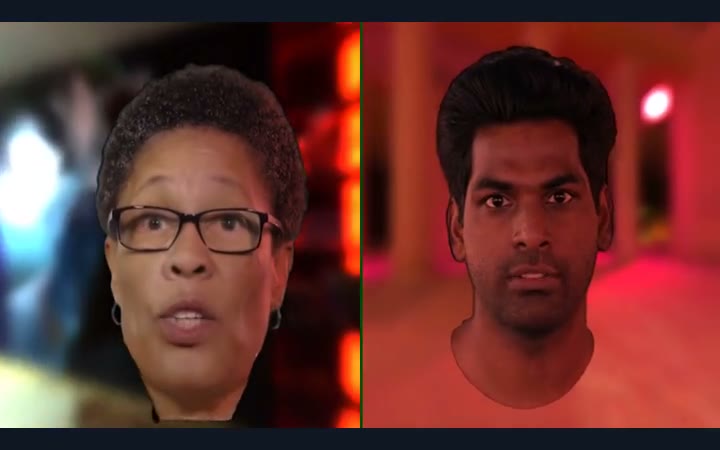
Animatable 3D head avatars from monocular video, with realistic relighting and editable materials.
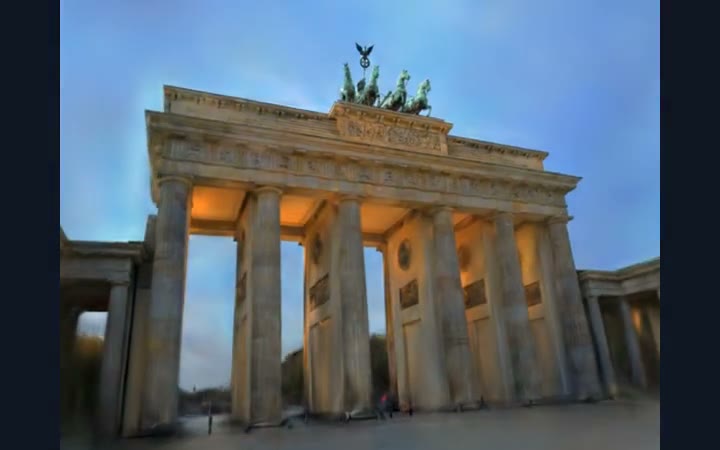
Reconstructing 3D scenes from in-the-wild photo collections, with separated intrinsic and dynamic appearance.
Research Intern
Research Intern · Advised by Yu Li and Yunfei Liu